How to refuse only AI training in robots.txt: __usage_ai-training, and how many top Japanese sites have written it (November 2026)
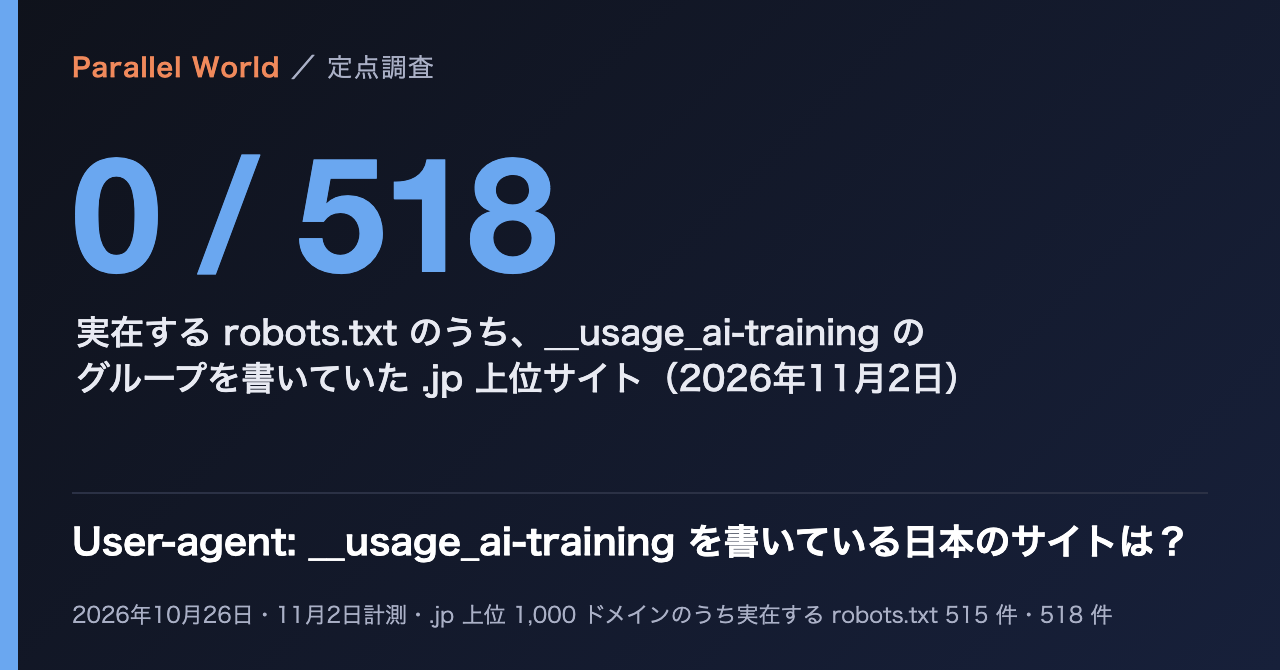
In a survey on 2 November 2026, 0 of 518 robots.txt files from top Japanese .jp sites contained __usage_ai-training (weekly census of Parallel World, migurei.ai).
The announcement was on 30 October 2026 and the survey was three days later. Each company's support is scheduled to start over the period up to 2027, so this is a count from before they read it.
How to write it
Add a group named __usage_ai-training to robots.txt. It is written like any other bot group, in two lines:
User-Agent: __usage_ai-trainingDisallow: /
To allow only part of the site, add Allow. The ITmedia article gives Allow: /press-kit/ as an example.
A User-Agent: * group does not apply to this name. A site with no such group has stated no preference about AI training.
The name comes from an individual IETF draft, not a document of a working group: https://datatracker.ietf.org/doc/draft-kelley-aipref-training-preference-signal/
- Write the group
Disallow: /underUser-Agent: __usage_ai-training - Allow part if neededExample:
Allow: /press-kit/ - Companies read itGoogle aims for 2027, Microsoft from 1 February 2027, OpenAI aims for the coming months
Source: "How to write it" and "When each company starts reading it" in the text (November 2026). Start dates are the companies' announcements; nothing reads it yet.
When each company starts reading it
| Company | What it announced (original wording) | Source |
|---|---|---|
| "We aim to support this new control along with other AI providers in 2027" (no date) | Google Search Central blog | |
| Microsoft | "Starting February 1, 2027, Microsoft will honor the new preferences as it crawls" | Bing Search blog |
| OpenAI | "We aim to implement the signal in the coming months" (no date) | OpenAI |
Google plans to treat this group as a refusal like Google-Extended for sites that do not name Google-Extended separately.
Anthropic: a person working there submitted the draft under their own name. As of 2 November 2026 we found no document on Anthropic's own pages that commits it to support.
Bing separates training from use in AI answers (grounding). Training is the robots.txt group above; grounding is set per page (for example <meta name="Bingbot" content="ai-grounding:disallow">), and both are read from 1 February 2027.
Where the numbers come from
Every week we read the robots.txt of 1,000 top Tranco .jp domains and count what they say. The 518 here are the sites whose robots.txt came back with a 2xx status from the site's own domain and had at least one directive.
- 26 October 2026 (before the announcement): 0 of 515
- 2 November 2026 (three days after): 0 of 518
The research page and the weekly CSV:
The public CSV shows counts under 5 as "<5". The 0 in this row is the value we counted from the stored robots.txt text.
What these numbers do not say
- They are not a share of all Japanese sites. They count 518 of 1,000 top .jp domains for which a real robots.txt was obtained. We cannot tell from this number what is going on with the other 482 (482 is 1,000 minus 518, our arithmetic).
- They do not show that sites allow AI training. Not writing the group means no preference stated, not consent.
- It is one survey three days after the announcement, before the companies read it. Whether the count will rise is not something this number says.
- They count what is written in robots.txt, not whether what is written was obeyed.
- We read the Bing announcement through a summary. Check the original before you decide what to write.
About us
This article is written by the Parallel World (migurei.ai) operations team. Our work measuring how a site looks to AI agents is on the Parallel World page.
FAQ
If I write __usage_ai-training in robots.txt, can I refuse AI training right now?
We cannot say that for today. By the companies' own announcements, Google aims to support it in 2027, Microsoft will honor it as it crawls from 1 February 2027, and OpenAI aims to implement it in the coming months. For Anthropic, we found no page of its own as of 2 November 2026. If you write it now, it is expected to be read as your preference once each company starts reading it.
How many Japanese sites refuse AI training by naming bots such as GPTBot?
In our survey of 26 October 2026, before the shared name was announced, of 719 top .jp sites with a robots.txt verdict, 111 (15.4%) refused at least one of 9 training bots by name and 34 (4.7%) refused all 9. You can check the numbers in the weekly CSV: https://pw.migurei.ai/data/japanese-sites-and-ai-bots/2026-W44.csv